io.github.hcarrillo001/retrieval-mcp
Docker image ghcr.io/hcarrillo001/retrieval-mcp
Source & Apache 2.0
A local-first LLM-eval server for Claude or your CI pipeline. Score RAG by stage, author metrics in plain language, and track every run. Try a real eval below, no signup.
Run a real eval right here, no signup. Pick a sample (or paste your own input, context, and output), choose a free judge model, and watch retriEVAL score it. Nothing is saved.
Runs on a free model · nothing is saved · limited per day
The metrics aren't new; DeepEval and Ragas cover those. The shape is: a standalone, local-first MCP an agent can call mid-workflow, with RAG scored by stage.
contextual_recall flags retrieval misses; faithfulness flags hallucinations. Know which half to fix, not just "the answer is bad."
Connect it like any other tool and score outputs, author metrics, and pull up charts by asking. retriEVAL is the scoring engine your workflow reaches for.
Run free on a local Ollama model, or plug in your own Claude, OpenAI, or any OpenAI-compatible LLM key. No platform account, no data leaving your box.
Every run is saved (file or Supabase). Trend by model, compare runs, drill into the case that regressed, on a dashboard you own.
No pipeline required. Connect retriEVAL in Claude or another chat UI, toggle it on, and a manual tester can score outputs and author metrics in plain language. Every result links straight to the run in the dashboard.
Illustration. Uses the hosted server, since chat UIs connect to remote MCPs.
Self-hosted. Clone it, point it at a judge, run it. Your data never leaves your machine.
git clone https://github.com/hcarrillo001/retrieval-mcp
cd retrieval-mcp
pip install -r requirements.txt
# pick a judge, or use a local one below
export ANTHROPIC_API_KEY=sk-ant-...
python server.py
# in the chat: paste your cases inline "Score these cases with faithfulness: [{"input": "...", "actual_output": "...", "retrieval_context": ["..."]}]" # nothing is stored, no setup step
Pick your judge: free local Ollama (RETRIEVAL_JUDGE_BACKEND=ollama) to keep everything on your machine, or your Anthropic key, your OpenAI key, or any OpenAI-compatible endpoint via OPENAI_BASE_URL. Full setup, including your own always-on instance with a dashboard, is in the repo README.
A full walkthrough, plus the three steps to run it yourself in Cursor.
Run retriEVAL locally as an MCP server in Cursor.
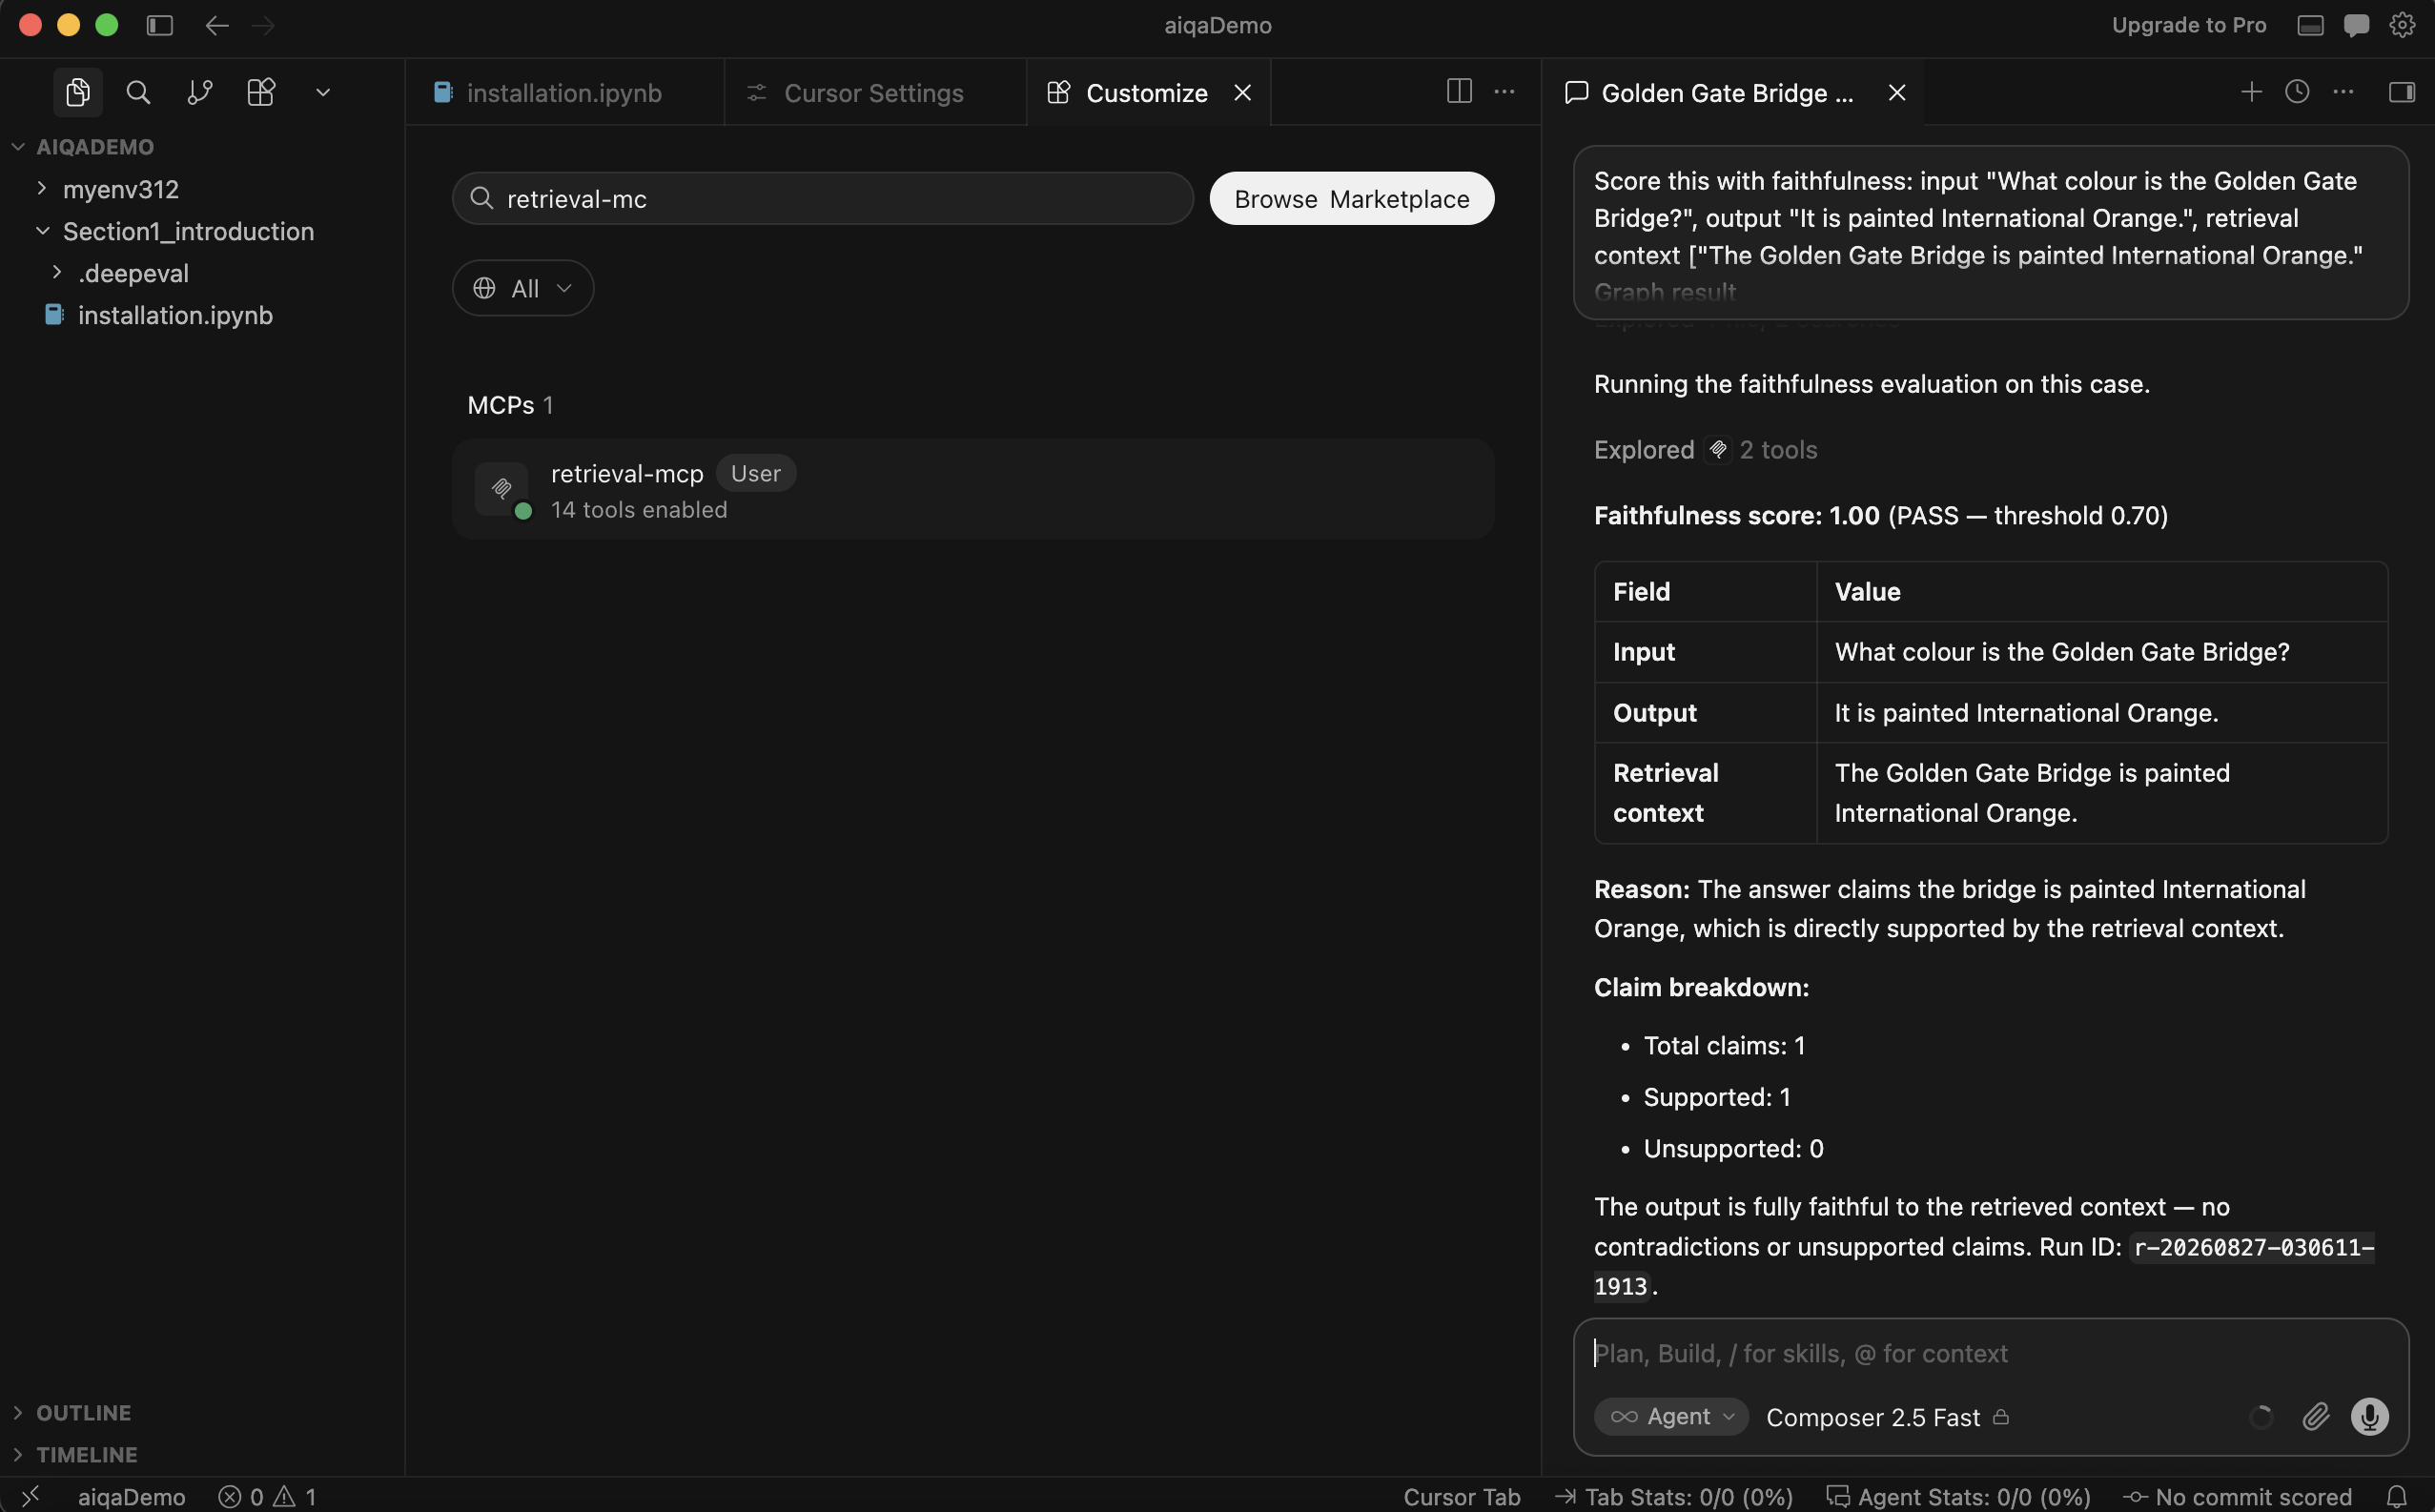
What you're aiming for: connected in Cursor, green dot, 14 tools enabled.
Copy, paste, run. About two minutes, and you need Docker Desktop plus a judge key (an Anthropic key here, or skip it and run a local model, see below).
mkdir -p ~/.cursor && cat > ~/.cursor/mcp.json <<'EOF'
{
"mcpServers": {
"retrieval-mcp": {
"command": "docker",
"args": ["run", "-i", "--rm", "-e", "ANTHROPIC_API_KEY",
"ghcr.io/hcarrillo001/retrieval-mcp:1.0.0"],
"env": { "ANTHROPIC_API_KEY": "sk-ant-PUT-YOUR-KEY-HERE" }
}
}
}
EOF
Already have a ~/.cursor/mcp.json? This overwrites it, so paste the retrieval-mcp block into your existing file instead.
open -a Cursor ~/.cursor/mcp.json
# replace sk-ant-PUT-YOUR-KEY-HERE, save, then:
python3 -c "import json;json.load(open('$HOME/.cursor/mcp.json'));print('valid json')"
retrieval-mcp with a green dot and 14 tools enabled.
Then paste this into the chat:
# in the Cursor chat: expect 1.00, all claims supported
Score this with faithfulness:
input "What colour is the Golden Gate Bridge?",
output "It is painted International Orange.",
retrieval context ["The Golden Gate Bridge is
painted International Orange."]
No green dot? Docker wasn't running when Cursor started. Start
it and restart Cursor. Want to keep everything local? Add
"RETRIEVAL_JUDGE_BACKEND": "ollama" to the
env block, drop the API key, and no data leaves your machine.
Runs are written inside the container, never to a hosted database.
Prefer to try it yourself? Run a live eval in the sandbox. No signup.
Honest positioning: not "better metrics," but a different shape: standalone, local, and usable as a tool inside an agent.
| retriEVAL | Hosted eval platforms | Eval libraries | |
|---|---|---|---|
| Works as an MCP tool inside an agent | yes | platform-gated | no |
| Runs local, no account | yes | no | yes |
| Bring your own model / key (Ollama, Claude, OpenAI, …) | yes | limited | yes |
| RAG scored by stage, built in | yes | varies | manual |
| Own dashboard + history | yes | yes | no |